 By Mark
Bringing AI into enterprise security infrastructure changes the model itself: instead of deterministic, rule-based protection, you’re managing adaptive, probabilistic behavior. Traditional security relies on static boundaries and fixed authentication gates. AI-driven runtime environments don’t play by those rules. Model behavior is inherently non-deterministic, so static checks alone aren’t enough anymore.
Adapting existing security practices to this means adding hybrid search and retrieval-validation layers that control what enters the model’s context.
In that setting, hybrid re-ranking can act as a security control. The math for combining vector and keyword retrieval is well known; what matters for security is that re-ranking decides which documents reach the context window of a RAG system.
Adding a second validation and ordering step over unstructured inputs can reduce hallucinations and help enforce data-protection boundaries. This post covers the architecture, how the scores are combined, and where authorization fits in.
Scope of this post: the part that connects directly to security is Section 3 (authorization-aware pre-filtering and row-level security). Sections 1-2 are a general re-ranking overview, so if you know it already, skip to Section 3. This post has no performance numbers I measured myself; an implementation example is in [Bastion-RAG 3] Hybrid Reranking.
Series: [The AI Shield] Advanced AI Security and Data Governance Architecture
- System Configuration and Filtering
- Prompt Injection Defense Design
- Metadata Filtering
- Hybrid Reranking (Here!)
- Data Engineering and Preprocessing
- Mathematical Optimization and Advanced Defense
Table of Contents
Introduction: The Gatekeeper of AI Trustworthiness and the Necessity of Hybrid Search
In 2026, generative AI has transitioned from an experimental asset into core economic infrastructure reshaping enterprise decision-making. By pairing Large Language Models (LLMs) with massive internal corporate knowledge bases via RAG, organizations have seen exponential productivity gains—personally, I observe a 5x to 10x acceleration in knowledge discovery workflows. Yet, this rapid data synthesis introduces unprecedented risks regarding data sovereignty and system reliability.
Security architecture should be designed in from the start, not added afterward. In a RAG workflow, retrieval quality is the first gate for the system’s reliability, and relying solely on vector search can let subtle misinformation and compliance problems through. Hybrid re-ranking helps by combining lexical precision with semantic context.
1. Technical Mechanisms and Working Principles of Hybrid Re-ranking
Hybrid Re-ranking optimizes retrieval quality by combining the distinct strengths of traditional keyword-based matching and deep learning-based vector search. This combination can help reduce the chance of an LLM producing an ungrounded answer, improving the model’s faithfulness.
1.1. BM25: Lexical Precision and Exact Token Matching
BM25 (Best Match 25) is a highly reliable probabilistic algorithm that scores documents based on term frequency ($f$) and inverse document frequency ($\text{IDF}$). It remains unmatched when a query requires pinpoint accuracy for specific tokens, such as part serial numbers, proper nouns, unique product IDs, or precise legal terms.
The mathematical core of BM25 is formulated as follows:
$$\text{Score}(D, Q) = \sum_{q \in Q} \text{IDF}(q) \cdot \frac{f(q, D) \cdot (k_1 + 1)}{f(q, D) + k_1 \cdot (1 – b + b \cdot \frac{|D|}{\text{avgdl}})}$$
In this equation, $k_1$ regulates the term frequency saturation nonlinear limit, while $b$ dictates document length normalization, ensuring that longer documents do not artificially dominate search scores.
1.2. Vector Search: Dense Semantic Mapping and Intent Discovery
Vector search converts text chunks into high-dimensional dense embeddings to measure contextual similarity. This allows the system to identify highly relevant documents even if the user uses completely different vocabulary or synonyms to express their intent. Typically computed via Cosine Similarity, it evaluates the geometric angle between the query vector and document vectors to establish conceptual relevance.
2. Reciprocal Rank Fusion (RRF) and the Two-Stage Re-ranking Process
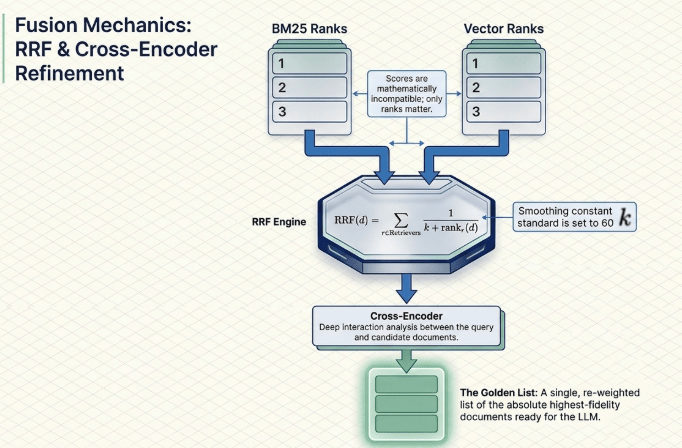
The true engineering challenge of hybrid retrieval lies in unifying these two entirely distinct scoring systems (BM25’s open-ended scale and Vector Search’s bounded similarity score) into a single, cohesive result list.
2.1. The Mathematical Integration of Reciprocal Rank Fusion (RRF)
RRF bypasses the issue of incompatible raw score distributions by evaluating only the relative rank of a document within each respective retrieval method.
The RRF score for a document $d$ is calculated using the following formula:
$$\text{RRF}(d) = \sum_{r \in \text{Retrievers}} \frac{1}{k + \text{rank}_r(d)}$$
Where $k$ is a constant multiplier (typically optimized around 60) that dampens the influence of low-ranking outliers.
2.2. Cross-Encoder Based Precision Re-ranking
While RRF creates a solid unified baseline, advanced architectures pass the top candidates to a deep-learning-based Cross-Encoder for a definitive evaluation.
- Stage 1 (Bi-encoder): Uses traditional embeddings and BM25 to independently scan millions of documents, surfacing a broad candidate pool (e.g., top 100 results) with minimal latency.
- Stage 2 (Cross-encoder): Feeds the query and each candidate document simultaneously into a highly specialized transformer layer. This layer performs an exhaustive cross-attention check to analyze deep token-to-token interactions, outputting a precise relevance score to determine the final ordering.
3. Authorization-Aware Retrieval Design from a Security Architecture Perspective
As a security practitioner, the principle I care most about is simple: “If a user does not have explicit permission to view a piece of data, the system should never retrieve it.”
3.1. Pre-filtering and Database Row-Level Security (RLS)
Modern secure RAG architectures reject post-retrieval filtering in favor of Authorization-aware Pre-filtering.
- Metadata Ingestion: During the data pipeline ingestion phase, immutable access control tags (such as
tenant_id,department_clearance, orallowed_roles) are appended directly to every distinct data chunk. - Deterministic Query Restriction: When a user submits a query, the application interceptor extracts their verified identity tokens from the IAM (Identity and Access Management) layer and injects these attributes directly as hard constraints into the vector database query.
- Enforcing Database-Level RLS: Forcing Row-Level Security directly at the database engine layer ensures that even if an intermediate LLM generates a flawed or manipulated retrieval query via an injection attack, the underlying data store physically bars access to unauthorized records.
3.2. Preventing Side-Channel Leaks in the Re-ranking Stage
The re-ranking layer must also operate strictly within the user’s verified security boundary. The cross-encoder model must only accept a candidate list that has already passed through the pre-filtering authorization checkpoint. Furthermore, raw re-ranking relevance scores must be guarded to prevent information leak vectors (side-channel analysis), where a malicious actor might infer the existence of a highly confidential document based on subtle variations in systemic latency or scoring shifts. Every step of this execution path feeds into the system’s immutably recorded Audit Trail, validating end-to-end compliance.
4. Enterprise Use Cases: Real-World Implementation and Security Triumphs
Hybrid re-ranking is widely used in search products, so the examples below are often cited. I haven’t verified these sources or figures myself, so treat them as illustrative.
4.1. Stack Overflow and Spotify: Optimizing Discovery
- Stack Overflow: Is reported to use a hybrid engine combining BM25 exact matching for rare error codes with dense vector models to decipher ambiguous natural language programming queries. This helps match intent even when developers lack the exact terminology.
- Spotify: Is reported to combine lexical matching with behavioral signals at the re-ranking tier to improve click-through on vague queries.
4.2. Adobe and Mercedes-Benz: Hardening Enterprise RAG
Adobe and Mercedes-Benz are reported to use hybrid RAG for technical manuals and legal documents: exact lexical matching for part and clause numbers, plus semantic search for intent. This is said to reduce hallucinations, though I couldn’t verify any figures.
5. Balancing Performance with Cost: Operational KPI Management
A resilient security design must also be operationally viable. Introducing cross-encoders and multi-stage retrieval can add computational overhead. Managing the following Core KPIs is vital for production deployments:
| Core KPI | Definition & Measurement | Hybrid Search Considerations |
| TTFT (Time to First Token) | Total latency elapsed before the LLM streams its first output token. | Heavily dependent on retrieval and re-ranking execution speeds. |
| Recall@K | The proportion of highly relevant documents captured within the top $K$ results. | Hybrid models consistently outperform pure vector indexes on this metric. |
| nDCG / MRR | Metrics evaluating the precision and positional relevance of top-ranked items. | Requires careful fine-tuning of RRF dampening constants ($k$). |
| Infrastructure Costs | RAM overhead for dense vector indexing and GPU compute requirements for cross-encoders. | Requires optimization of chunk allocation and resource provisioning. |
To effectively balance latency and infrastructure spend, production environments often implement Semantic Caching. High-frequency queries are evaluated against a cache of previously authorized results, cutting redundant GPU cycles and lowering average response times.
6. Regulatory Alignment and Compliance Mapping
Constructing an enterprise AI architecture requires alignment with emerging global compliance frameworks:
- NIST AI RMF 1.0: Focuses heavily on managing systemic risk across the entire AI lifecycle. Hybrid re-ranking serves as a technical control directly fulfilling the ‘Govern’ and ‘Mitigate’ criteria by ensuring data traceability.
- ISO/IEC 42001:2023: Establishes a verifiable Artificial Intelligence Management System (AIMS). It demands structured operational controls, making multi-stage retrieval audits a core component of continuous risk evaluation.
- EU AI Act: Enforces strict compliance mandates on high-risk AI deployments, legally requiring data provenance, technical documentation, and rigorous logging.
By utilizing a hybrid re-ranking pipeline, the system generates precise grounding logs for every extracted source document. This provides the concrete audit trail necessary to satisfy independent compliance reviews.
Conclusion: Securing the AI Frontier Through Engineered Resilience
Building a trustworthy AI system is not about adopting a single tool; it takes governance and technical controls working together. My takeaway from working through this is that hybrid re-ranking, combined with authorization-aware retrieval, can make retrieval more auditable and predictable.
By anchoring semantic vector models with the concrete precision of lexical matching, and layering it with authorization-aware pre-filtering, an enterprise can confidently unlock the value of its private data. Security is never a static target; it is a continuous process of measuring, auditing, and hardening.
In our next installment of [The AI Shield], we will shift our focus to Part 4: Data Engineering & Pre-processing, where we will explore multi-tenancy isolation and deterministic data de-identification strategies across the broader ingestion lifecycle.
Final Engineering Reflection
For an engineer who grew up on low-level code and hard logic, ranking and scoring systems feel counterintuitive. In my earlier experience, ranking algorithms were hard to fit reliably in production. I now think better statistics and rebalancing methods make them more manageable, and I want to explore this further.